Document-to-Speech NLP Pipeline
Multi-Linguistic Audio Solution
NLP document ingestion and audio synthesis platform converting multi-lingual PDFs into natural speech across 10+ languages.
5-page PDF -> 55 min audio
10+ languages supported
Team of 4 led
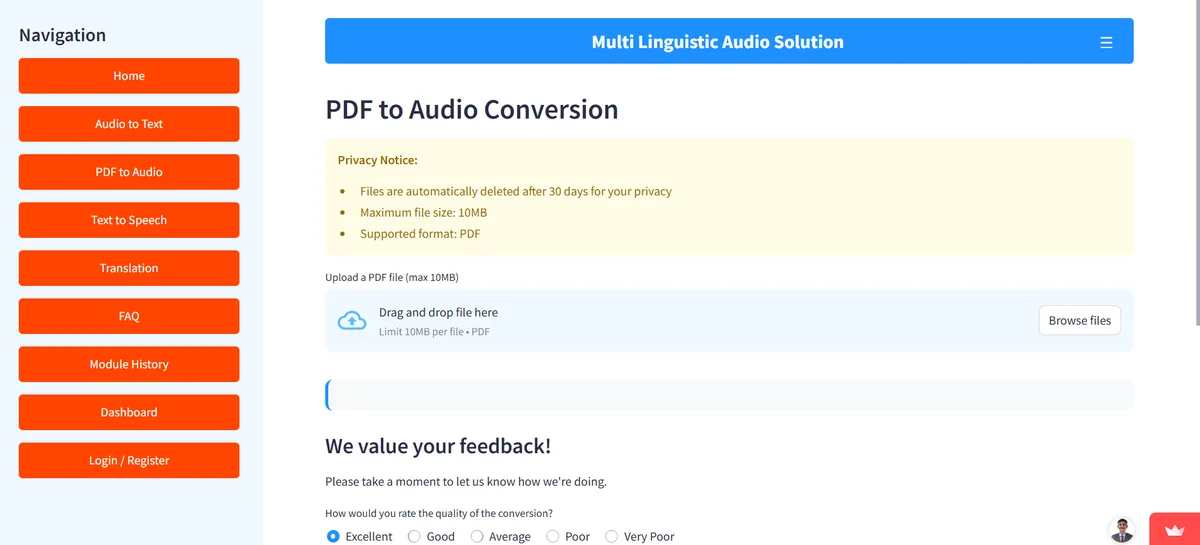
Architecture & System Implementation
Led a team of 4 engineers to develop an end-to-end natural language processing pipeline that converts complex multi-lingual documents into high-quality spoken audio. The system parses dense PDF files, cleanses formatting artifacts, detects language shifts, and synthesizes continuous audio output. Successfully transformed a dense 5-page PDF document into 55 minutes of continuous audio across 10+ regional and international languages.
Core Features & Capabilities
- Robust document ingestion extracting text from formatted PDFs and image scans
- Speech-to-text transcription and multi-lingual text-to-speech synthesis across 10+ languages
- Multi-language translation engine enabling cross-lingual audio generation
- Integrated MongoDB database for caching synthesized audio chunks and user transcripts
- Interactive Streamlit web interface with audio playback, scrubbing, and download controls
Engineering Contributions & Optimizations
- Led development sprint planning and code reviews across the 4-engineer project team
- Designed text chunking heuristics to preserve prosody and sentence cadence during synthesis
- Optimized document ingestion speed and configured MongoDB audio metadata persistence
Technologies & Libraries
PythonStreamlitNLPSpeech SynthesisMongoDBgTTS
REST API Endpoint
200 OKThis project is programmatically queryable via our public JSON API:
curl -s https://rajatsurana.vercel.app/api/projects/multi-linguistic-audio-solution