Custom Search Engine & Web Crawler From Scratch
RS-Engine
Built a complete web search engine from scratch with a concurrent crawler, inverted indexing pipeline, and TF-IDF relevance ranking.
Custom TF-IDF ranking
Multi-threaded crawler
Zero external search libraries
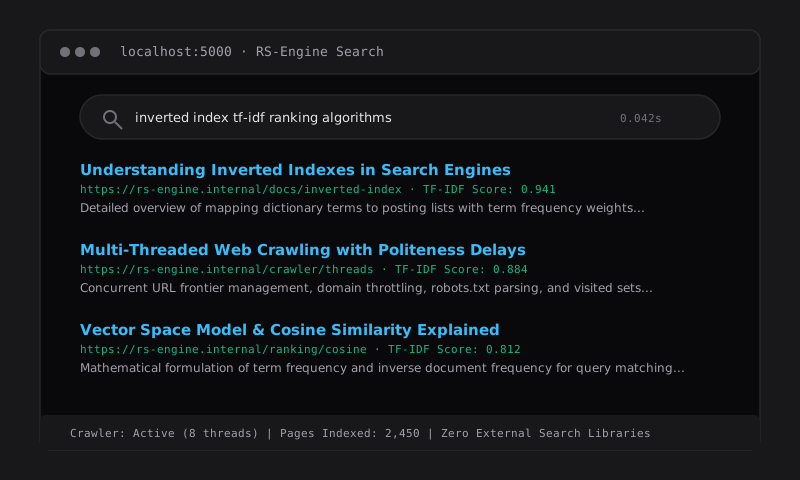
Architecture & System Implementation
Engineered an information retrieval system from fundamental computer science principles. Implemented a concurrent, multi-threaded web crawler with URL frontier management and politeness delays, an indexing engine that tokenizes documents and eliminates stopwords, and a vector space TF-IDF scoring algorithm that ranks web pages against search queries with a Google-inspired Flask web UI.
Core Features & Capabilities
- Concurrent multi-threaded crawler with domain throttling and depth limits
- Inverted index data structure mapping tokens to document posting lists with term frequencies
- TF-IDF relevance algorithm scoring cosine similarity between query and documents
- Tokenization, lowercasing, punctuation stripping, and stopword removal pipeline
- Clean, responsive Flask web application for query execution and result previewing
Engineering Contributions & Optimizations
- Built custom inverted index serialization and fast in-memory posting list lookups
- Implemented thread-safe visited URL sets to prevent crawling cycles
- Optimized score computation using sparse term frequency vectors
Technologies & Libraries
PythonFlaskMulti-ThreadingInverted IndexTF-IDFHTML5
REST API Endpoint
200 OKThis project is programmatically queryable via our public JSON API:
curl -s https://rajatsurana.vercel.app/api/projects/rs-engine